
Quick answer: Search engines discover web pages, crawl their content, and analyze selected pages for inclusion in an index. When someone searches, ranking systems retrieve and order relevant results from that index. Discovery does not guarantee indexing, and indexing does not guarantee visibility: results depend on the query, content, and search context.
Key facts
- Google describes three stages: crawling, indexing, and serving search results. In-depth guide to how Google Search works
- Google renders pages and executes JavaScript using a recent version of Chrome. In-depth guide to how Google Search works
- A sitemap supports URL discovery but does not guarantee crawling or indexing. Learn about sitemaps
- Google ranks results programmatically and does not accept payment for higher organic rankings. In-depth guide to how Google Search works
TL;DR: Identify whether a page has a discovery, crawling, indexing, or ranking problem before choosing an SEO fix.
- Crawling
- The process in which a search engine bot requests and downloads content from discovered URLs.
- Rendering
- Processing a page, including executing supported JavaScript, to expose content that may not appear in its initial HTML.
- Indexing
- Analyzing content and storing selected information in a searchable index.
- Ranking
- Ordering eligible results for a particular query using relevance, quality, and contextual signals.
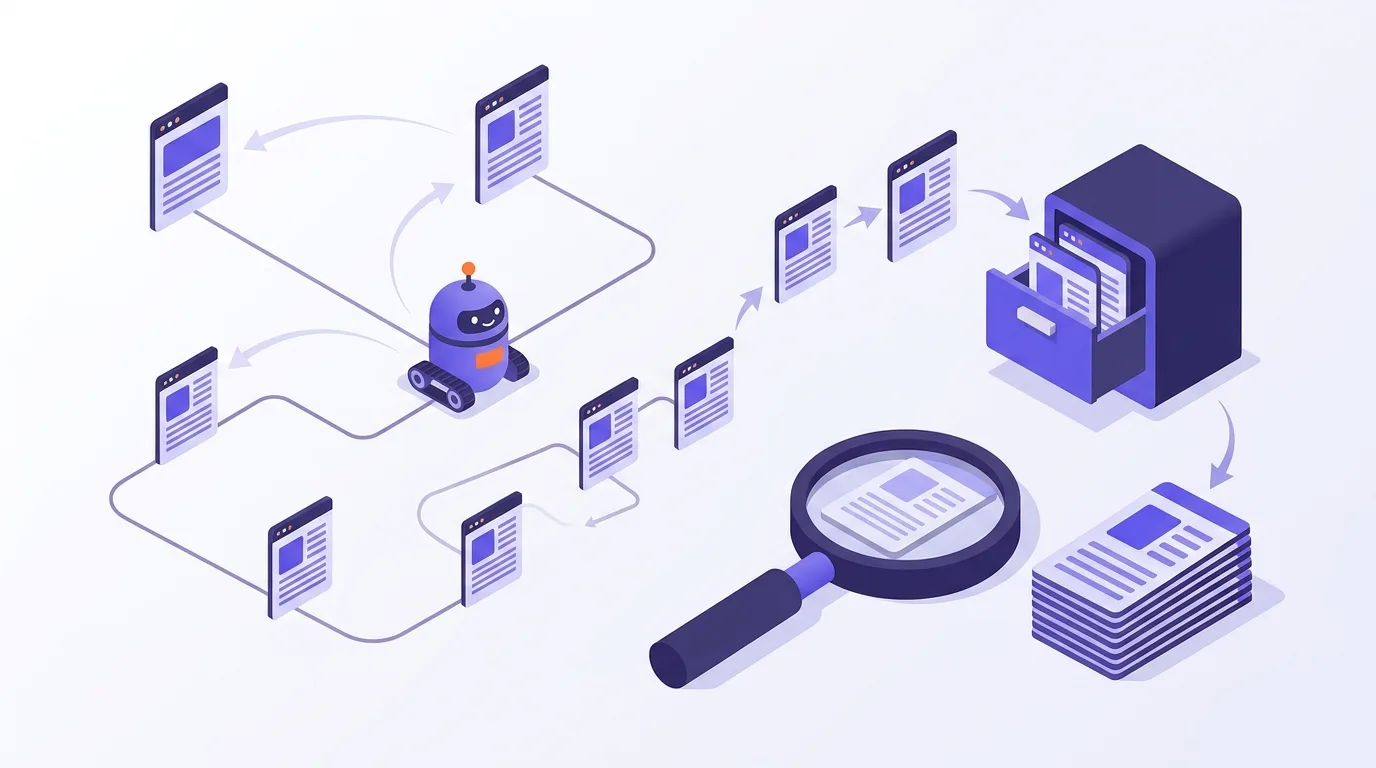
How do search engines work?
Search engines work through a crawl–index–rank process: they fetch pages, analyze selected content for an index, then retrieve and order matches for a query. Google’s official final stage is called serving, which includes ranking and presenting results, as explained by Google Search Central.
Google Search and Bing are search engines, but their systems differ. A crawler, such as Googlebot, fetches content for processing. The search engine analyzes it for inclusion. Its search index is a searchable representation of selected content, not a complete copy of the web.
URL discovery precedes crawling. Rendering exposes content for processing: Google executes JavaScript using a recent version of Google Chrome, according to Google Search Central. These distinctions add detail, not conflicting stage counts.
A newly published guide illustrates the lifecycle:
- Crawling: After discovery, a bot may fetch the guide.
- Indexing: The engine analyzes its content and decides whether to include it.
- Serving: Query retrieval finds indexed matches; ranking orders them. The guide may appear for a relevant search.
SEO helps search engines understand content; eligibility does not ensure inclusion or visibility.
Why the stages matter for SEO
This section explains why SEO diagnosis must distinguish a known URL, fetched content, indexed information, and a result shown for a query.
Google Search separates crawling, indexing, and serving; progress at one stage does not ensure progress at the next (Google Search Central).
| State | Practical meaning |
|---|---|
| Known URL | The engine has discovered the address, not necessarily its content. |
| Fetched content | Crawling retrieves content for processing. |
| Indexed information | Content has entered the search index; index eligibility alone does not ensure inclusion. |
| Shown result | The engine selects the page for a particular search. |
Consider a waterproof boots product page. If it has not been fetched or processed, its absence differs from an indexed page missing from results for “boot repair.” Google assesses relevance and quality alongside search context (Google Search Central).
Diagnose the stage before changing the page. Better relevance cannot fix blocked access. Successful crawling alone cannot establish relevance.
SEO helps search engines understand useful content and helps people find it through search.
How do search engines discover and crawl pages?
Search engines discover pages through links and URLs they already know. A crawler then requests page content from the site’s server. Googlebot, Google Search’s crawler, accesses pages and follows links to find more content; fetching content is crawling, as described by Google.
Links help crawlers find pages
Orphaned pages lack internal links pointing to them, leaving no path from other site pages. Important pages need crawlable internal links so crawlers can find them, as Google recommends.
Rendering processes fetched content
Rendering builds a page from fetched content and resources. Google uses a recent version of Google Chrome to execute JavaScript during rendering, according to Google; see JavaScript SEO for implementation details. Access to page resources can therefore matter, but rendering does not prove that every script-dependent interaction will work.
Crawlability and crawl budget covers crawl scheduling and access troubleshooting; Google’s advanced budget guidance mainly targets very large, frequently updated sites or sites with many discovered but unindexed URLs, per its crawl budget guide.
What happens when a page is indexed?
When a page is indexed, the search engine analyzes its fetched content and stores selected information in a search index for later retrieval. Indexing is more than adding a URL to a list: it involves understanding the content and deciding what to retain, as Google Search Central explains.
Eligibility is not inclusion
Indexability means eligibility to be included in an index. A technically eligible page may still not be selected for inclusion. Access to its content makes processing possible; it does not mean the engine will store that content.
For indexing controls and exclusion troubleshooting, see indexability and noindex.
Similar pages can share a representative
Similar pages can form a group rather than appear as entirely separate results. Google selects a representative URL using signals, including canonical annotations, which express a preference rather than force its choice, according to Google Search Central.
Returning to the guide example: the engine may fetch and process the guide without yet including it in the index. A successful fetch alone does not establish inclusion.
How are results ranked and served?
Results are ranked and served by retrieving relevant candidates from the search index and ordering them for the current query. Systems assess which pages best fit what someone is looking for, then return selected results. Google Search calls this stage serving, as described in Google’s documentation.
Why results vary
Relevance, quality, and search context are broad inputs, not a public scoring formula; location, language, and device can affect Google’s results, so a page has no universal rank, according to Google Search Central.
Advertising is separate from organic selection: Google does not accept payment for higher organic rankings, as Google Search Central explains.
Search intent is the goal behind a query.
Result formats are the ways search results appear.
AI-generated answers synthesize information rather than simply list matching pages.
For example, an indexed bicycle repair guide could suit “how to fix a puncture” but not “bicycle repair shop nearby.” Successful crawling does not make that guide the right result for both queries.
Common mistakes about crawling, indexing, and ranking
This section covers common mistakes that blur the differences between discovery, crawling, indexing, and ranking.
- These statuses are not interchangeable. A known URL is not necessarily fetched, and fetched content is not necessarily indexed; Google Search treats crawling, indexing, and serving as distinct stages, as explained in Google’s search documentation.
- A sitemap is not an inclusion list. Submitting XML sitemaps helps URL discovery but does not ensure crawling or indexing, according to Google’s sitemap guidance.
- A crawl block is not a search exclusion. Robots.txt controls crawling, but a blocked URL can still appear in search if discovered through other links, as Google explains.
- Noindex is not a crawl-control substitute. Googlebot must be allowed to crawl a page to detect its noindex instruction, according to Google’s noindex guidance.
- Progress is not a fixed timetable. Treat promises of indexing or rankings by a set deadline with caution; completing an SEO task does not establish when either outcome will happen.
How to check which stage needs attention
This section covers how to identify which search stage needs attention.
Google Search separates crawling, indexing, and serving, so check evidence for each stage separately (Google Search Central).
Use Google Search Console’s URL Inspection, Page indexing, and Performance reports as your primary sources for Google-specific page status and search impressions.
| Stage | Observation | What it establishes | What it cannot establish |
|---|---|---|---|
| Discovery and fetching | Known URL; verified Googlebot server-log request | Discovery; evidence of a fetch attempt | Index inclusion |
| Index inclusion | Search engine reports page indexed | Reported index status | Target-query impressions |
| Search visibility | Reported search impressions | Visibility in reported searches | Visibility for every target query |
A successful live fetch does not prove index inclusion. Index inclusion does not prove impressions for a target query. No impressions alone cannot distinguish missing indexing from weak query demand or visibility.
Route access and discovery problems to the crawlability guide.
Route index-exclusion problems to the indexability guide.
Identify the stage, inspect relevant evidence, then follow the specialist guide rather than applying every SEO fix.
Frequently asked questions
Is Google Search a search engine or a web browser?
Google Search is a search engine, not a web browser. It finds and organizes web content, then returns results relevant to your query, as explained by Google Search Central. A browser, such as Chrome, is the app you use to open websites. You can use Google Search within a browser.
How long does it take a new page to appear in search results?
A new page has no fixed waiting time before it appears in search. Google must discover, crawl, and index its content before it can serve that content as a result, as explained by Google Search Central. Link to the page from relevant pages on your site. Discovery alone does not mean the page will be indexed or shown.
Do Google and Bing share the same search index?
Google and Bing maintain separate search indexes. An index is the collection of information a search engine stores about content it has processed. Both engines can include the same public pages, but inclusion in Google does not mean inclusion in Bing. Their results can differ because they discover, process, and rank content independently.
Can an outdated version of a page still appear in search?
An outdated search result can reflect information stored before a page changed. Updating your website does not instantly update a search engine’s index. Google needs to crawl and process the changed content through its search system, described by Google Search Central. Until then, a result may show older information even though visitors see the updated page.