
Quick answer: Duplicate content is identical or substantially similar main content available at different URLs, either within one website or across websites. Ordinary duplication is not a Google spam violation. Search engines usually select a representative URL, so managing duplicates means identifying unnecessary copies, preserving genuinely useful differences, and choosing an appropriate consolidation approach.
Key facts
- Some duplicate content is normal and does not violate Google’s spam policies. What is canonicalization
- Google selects a representative URL for duplicate pages; a site’s canonical preference is a hint, not an instruction. What is canonicalization
- Consolidating duplicates can combine incoming-link signals and reduce crawling of redundant versions. How to specify a canonical URL with rel="canonical" and other methods
- Blocking a duplicate URL in robots.txt does not guarantee that it stays out of Google’s index. How to specify a canonical URL with rel="canonical" and other methods
TL;DR: Group URLs by their main content, decide which differences genuinely help users, and consolidate unnecessary copies while preserving useful pages.
- Duplicate content
- Identical or substantially similar main content accessible through different URLs on the same or different websites.
- Near-duplicate content
- Main content that is largely the same despite small differences in wording, layout, or page attributes.
- Duplicate cluster
- A group of URLs identified as containing identical or very similar main content.
- Canonical URL
- The representative URL a search engine selects from a group of duplicate or very similar pages.
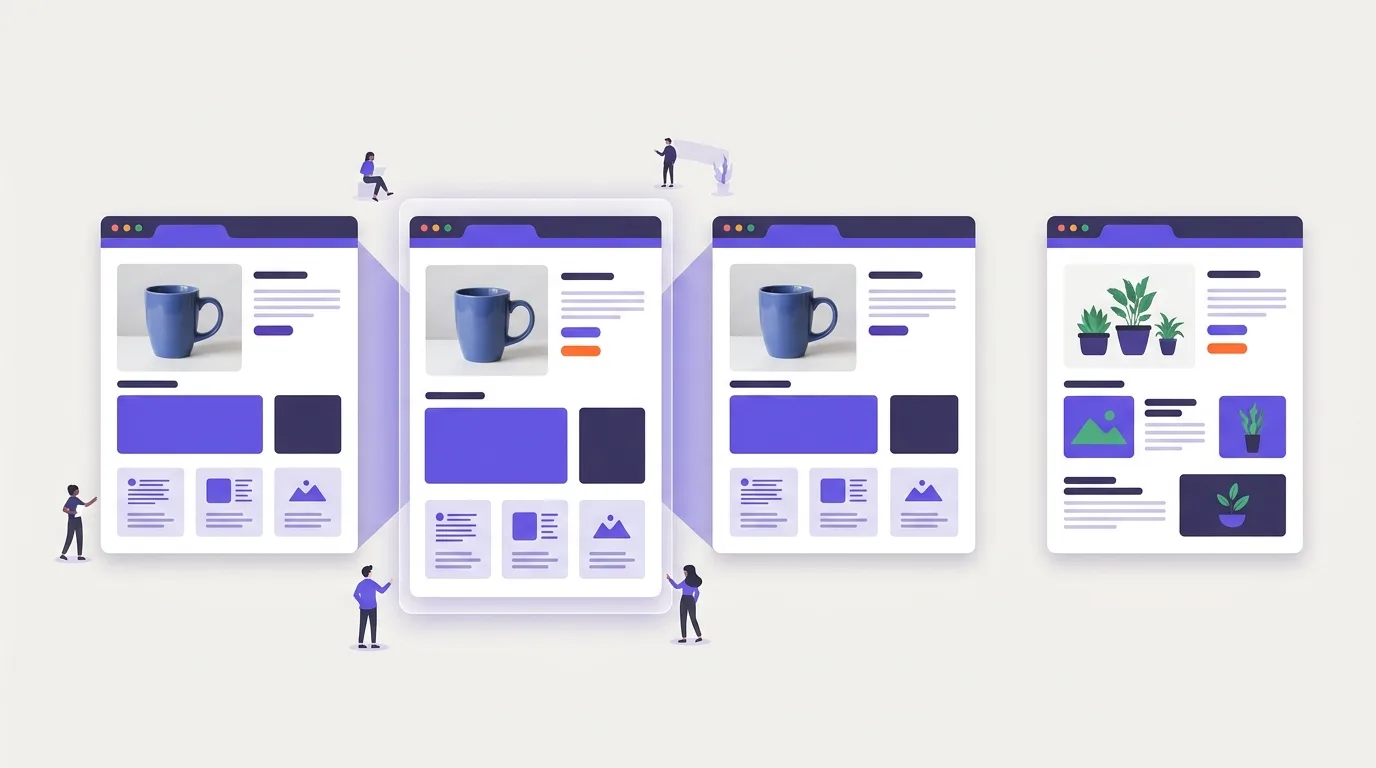
What is duplicate content?
Duplicate content is main content that is the same, or nearly the same, at different URLs. These URLs may be on one website or on different sites. Compare the content readers use, not just page titles, keywords, or shared menus.
For example, /products/blue-mug and /products/blue-mug?utm_source=newsletter may show the same product page. The tracking code changes the URL, but not the main content.
- Exact duplicates: The main content is the same across URLs.
- Near duplicates: The main content has only small differences.
- Internal duplication: Copies appear on the same website.
- Cross-site duplication: Copies appear on different websites.
Some duplicate content is normal and does not break Google’s spam rules, according to Google Search Central. Not every repeated passage needs a fix.
Google groups pages whose main content is the same or very similar. It then chooses a main URL, called the canonical URL. You can state which URL you prefer, but Google treats that choice as a hint, not a rule. See Google’s guide to canonicalization.
Keyword cannibalization is a different issue. It concerns pages that compete for the same search terms, even when their content differs.
Why does duplicate content matter for SEO?
Duplicate content matters because Google may show a different URL from the one you prefer, while extra copies can complicate crawling and maintenance. The key distinction is between normal duplication and copies that create a practical problem: not every repeated page needs consolidation, and a fix does not imply higher rankings.
Practical concerns
- The wrong URL may appear: Google may select a version you would rather not show.
- Copies take work to maintain: You may need to edit the same text in several places. Over time, those copies can fall out of sync.
- Link signals may be spread across copies: Canonicalization can bring signals such as incoming links together at a preferred URL, according to Google’s guidance. This does not mean traffic will rise.
Canonicalization can also reduce time spent crawling duplicate versions, according to Google Search Central. Use crawl-budget diagnosis to assess whether this matters for your site.
A duplicate left out of search is not always an error. Nor does fixing duplicate content promise better rankings. Measure visits and search clicks separately, as described in the checks below.
For broader context on changes to Google Search, see our overview of Google algorithm updates.
Where duplicate content comes from
Common sources include extra URL versions, copies made by a content management system, and reused text.
Alternate URL access paths
The same page may be available at several addresses. Examples include /product and /product?utm_source=email. Session codes, HTTP and HTTPS versions, and addresses with or without www can also create extra paths to the same content.
See URL structure for ways to keep page addresses consistent.
CMS-generated copies
A content management system, or CMS, may create extra views of a page. Print views are one example. Tracking codes and session IDs can also produce extra URLs.
Check sort options, filters, and product choices with care. A new URL does not prove that a page is a duplicate. Compare the main content and user need before merging pages for colors, sizes, filters, or regions.
Repeated editorial content
Whole articles or large blocks of text may be reused across pages or websites.
For language versions, check the main text. If only the menus are translated, the pages may still be duplicates. A true translation of the main text is not a duplicate just because it shares the same meaning. This distinction comes from Google Search Central.
Publishing an article on another site also creates a copy. See content syndication for more on planned reuse.
How can you find duplicate content on your website?
Collect your URLs, compare their main content, and group likely copies. Then check sample pages by hand to distinguish genuine duplicates from pages that serve different user needs. A tool can flag matching text, but shared menus, layouts, or product details alone do not establish that a page needs a fix.
A focused duplicate-content workflow
- Collect URLs. Gather addresses from your crawl, sitemaps, and CMS. Include URLs with parameters and product options.
- Set up content checks. In Screaming Frog SEO Spider, set up exact- and near-duplicate checks. Compare the main text, not just titles, menus, or page layouts.
- Check each group. Open sample pages and compare them. For filtered pages, look for changes in products, stock, and useful details. A tool warning or a missing canonical tag does not prove there is a problem.
- Make an issue sheet. Record the URLs, cause, key differences, preferred URL, planned action, and person responsible.
- Choose what to fix first. Start where the wrong page appears in search, extra URLs keep growing, or copies confuse users.
A technical SEO audit covers wider checks across the site.
A content audit reviews the value and purpose of pages, including those that overlap without being duplicates.
Choose an action for each duplicate group
Ask whether users need each URL and whether its main content serves a different purpose. Then choose an action.
| Situation | Action |
|---|---|
| An extra URL is not needed, and a matching page exists | Redirect it to the matching page |
| Matching copies must stay available | Keep them and name a preferred canonical URL |
| Pages serve different needs | Keep them and make their value clear |
| Copies are useful, and Google has chosen the right URL | Make no change |
Use a permanent redirect when an extra URL is no longer needed and a matching page can replace it. For duplicate pages, redirects are a strong signal of your preferred URL, according to Google Search Central.
When matching copies must stay available, use rel=”canonical” to name the preferred URL. This is also a strong signal, while sitemap inclusion is a weak one, according to Google’s guidance. See Canonical Tags for setup details. As noted above, Google can still choose another URL.
When pages serve different needs, use content optimization to make each page useful. Add details that help readers, rather than just changing words.
No change is a valid choice when the copies serve users and Google has selected the right main URL.
If the CMS keeps making copies you do not need, fix the source of the problem. Keep alternate views that users still need.
Common duplicate-content mistakes
Avoid fixes that remove useful pages or send the wrong search signals.
- Merging by keyword or layout. Shared keywords or templates do not make pages duplicates. Check the main content before merging them.
- Changing words without adding value. Swapping words for synonyms does not create a new answer or meet a new need.
- Blocking copies in robots.txt. Robots.txt is not a way to choose a canonical URL. Blocked URLs can still be indexed without their content, according to Google Search Central.
- Using noindex to name a preferred page. Noindex removes a page from Search. Google recommends rel=”canonical” instead when you want to state a canonical preference within your site. See Google’s guidance.
- Pointing a whole page series to its first page. Each page in a paginated series needs its own canonical URL. Google no longer uses rel=”prev” or rel=”next” to identify pagination relationships. Use crawlable links between pages, as described in Google’s pagination guide.
- Treating tool scores as rules. Do not use a tool’s uniqueness score or duplicate-content threshold as a Google ranking rule.
- Expecting automatic gains. Set goals you can test: redirects work, useful pages stay available, and canonical signals match your plan.
How do you verify that duplicate-content fixes worked?
Crawl the affected URLs again, compare each result with its planned action, and inspect Google’s selected canonical where available. A successful technical change does not require every copy to disappear: some should redirect, while others should remain usable. Assess search visibility and traffic separately rather than treating correct implementation as evidence of growth.
- Test each action. Re-crawl the URLs with Screaming Frog SEO Spider. A redirected URL should lead to the chosen matching page. A copy kept with a canonical tag should still load and name the intended URL. A distinct page should stay available and contain the planned useful content. For a no-change decision, check that the page still works as intended. If you changed how the CMS creates URLs, test that change too.
- Check Google’s choice. Use indexed URL Inspection data in Google Search Console. Compare your declared canonical with Google’s selected canonical for sample URLs. Page source shows your tag, not Google’s final choice. See Google’s canonicalization guidance.
- Review excluded pages. Some duplicate-related indexing exclusions may fit your plan. Do not try to remove every exclusion.
- Measure traffic separately. Check which landing page appears in search. Review impressions and clicks across the whole URL group, not just a copy that no longer appears. In your analytics tool, compare visits to the affected pages as a group. Do not infer a traffic gain from a canonical change alone.
Allow time for Google to crawl and process the changes. These checks confirm how the fix behaves; they do not promise a ranking or traffic increase.
Frequently asked questions
Do repeated navigation menus, footers, and legal notices count as duplicate content?
Shared page elements do not, by themselves, make the main content a duplicate. Google groups pages based on the same or very similar primary content, according to Google Search Central. Keep useful shared elements and compare the main text.
Can I use a manufacturer’s product description on my store?
From an SEO perspective, a shared description is not automatically a problem. Google may group pages with very similar main content and choose a main URL, as explained in its canonicalization guide. Add useful product details, such as tested compatibility or practical buying advice, rather than just swapping words. This SEO assessment does not establish permission to reuse the text.
What if another website copies my article without permission?
For the SEO check, compare the main content and inspect Google’s selected canonical for your URL in Search Console. Follow the verification steps above to assess search visibility. These checks address how the pages appear in search, not whether the copying was authorized.
Does Google’s canonical choice decide who owns an article?
No. Canonical selection chooses a main URL for search, not an owner of the work. Google’s guide explains that search process. A canonical selection is not evidence of permission to reuse an article.